The Level 1 calibration layer utilizes temperature scaling on small labeled datasets to ensure that reported probability scores reflect actual accuracy rates. While this sounds like a niche technical detail, it actually solves one of the most frustrating problems in modern AI: the fact that Large Language Models are often confidently wrong. In 2026, as enterprises attempt to automate critical workflows, they frequently encounter models that hallucinate or fail to follow simple formatting rules, leading to broken pipelines and costly manual reviews. Nokia’s Applied Research team has addressed this head-on with the release of AnyJev, a library that transforms these unpredictable generators into disciplined decision engines. By shifting the focus from writing text to calculating the probability of specific choices, this tool provides the stability needed for production environments. This Python-based framework fundamentally changes how engineers interact with open-source models, prioritizing statistical reliability over creative flair.
Transforming Linguistic Patterns: Moving From Text to Logic
Adopting a philosophy rooted in System One decision logic, the framework draws inspiration from previous systems introduced by TypeSafe AI to standardize how questions are posed to neural networks. In a production environment, asking an agent to write out an answer often leads to a variety of failures, ranging from unnecessary preamble to the complete invention of non-existent categories. AnyJev circumvented these issues by redefining the interaction as a typed operation where the model was forced to evaluate a finite set of possibilities. This structural shift ensured that the resulting data was always valid and immediately usable by downstream software systems without the need for fragile regex patterns or secondary validation models. Consequently, the library provides a more stable interface for critical tasks like ticket routing or policy enforcement, where a wrong format is just as damaging as an incorrect answer, thereby stabilizing the automated pipeline and reducing the need for human oversight.
The system explicitly supports three primary question formats to cover the vast majority of enterprise use cases: choice, noul, and score. Choice questions allow for selection from a fixed list of labels, while noul questions simplify binary yes-or-no decisions into a more robust mathematical framework. To maintain high performance during the computationally intensive cyclic shifts, the library leverages prefix caching, which allows the model to process unique option rotations without re-processing the entire prompt. Because the library reads the internal probability distributions or logits of the model directly, there is no actual text generation occurring during the inference process. This technical shortcut not only speeds up the time to first token but also guarantees that the output remains strictly within the constraints of the user’s defined schema. By operating at the level of raw probability, developers gain a much clearer understanding of the model’s inner workings and its degree of certainty for every single task.
Addressing Model Inconsistency: Neutralizing Position and Label Bias
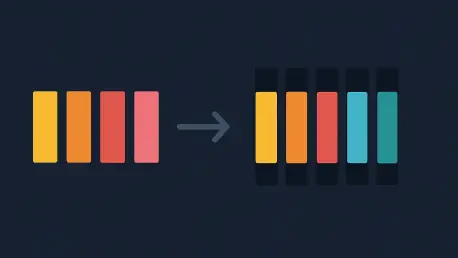
Despite the power of logit extraction, standard models frequently suffer from structural flaws like position bias and prior label tendencies that can skew results. Position bias occurs when a model disproportionately favors specific slots in a list, such as always preferring the first option simply because of its visual placement in the prompt structure. To combat these inconsistencies, the Level 0 calibration layer introduced a series of mathematical corrections that require no additional training. One primary technique involved the use of cyclic shifts, where the system rotated the order of options for each query to ensure every potential answer occupied every possible position. By calculating the geometric mean of these results in log space, the library effectively canceled out the additive effects of position bias. Furthermore, the library implemented batch calibration to subtract the model’s inherent prior tendencies from the final score, ensuring the decision process remained objective even when the underlying model had visible preferences.
Empirical testing using the Qwen3-8B model on high-density datasets demonstrated the profound impact of these calibration techniques on overall system performance. For instance, the sensitivity to option ordering dropped significantly, with flip rates falling from over twenty percent in raw configurations to less than eight percent when the Level 0 layer was active. Organizations looking to implement these tools should begin by identifying high-volume classification tasks where consistency is currently lacking and apply the L1 layer for maximum precision. Integrating these frameworks with prefix caching backends like vLLM will be essential to maintain low latency as task complexity increases. By adopting these mathematically grounded approaches, developers successfully transitioned from managing unpredictable text outputs to overseeing reliable decision engines. These advancements provided a clear roadmap for moving toward robust, production-ready systems that prioritize verifiable accuracy over simple generative flair, ensuring AI remains an asset in automated logic.