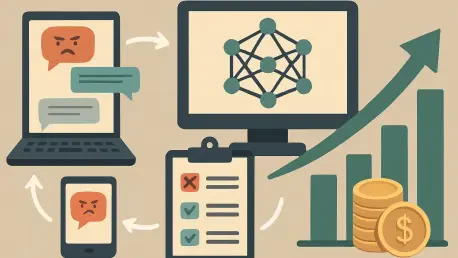
Current moderation systems must balance the high cost of server infrastructure against the necessity of removing abusive language in high-traffic public forums. As digital communities continue to expand throughout 2026, the sheer volume of threats and insults has made manual oversight nearly impossible, forcing a heavy reliance on automated classifiers. Traditionally, these artificial intelligence models have been measured by their performance on static test sets, primarily focusing on abstract metrics like F1-scores or accuracy percentages. However, a multidisciplinary research team from Concordia University, McGill University, and the University of Waterloo has identified a critical flaw in this approach: it ignores the real-world operational context. By partnering with the tech firm Scrawlr, these researchers developed the Profit-Driven Simulation (PDS) framework to evaluate how toxicity detection directly impacts platform engagement and long-term financial stability. This marks a significant shift from theory to industrial application.
The Failure of Static Metrics: Why Real-Time Dynamics Matter
Traditional evaluation methods test AI models against static datasets that are essentially frozen in time, providing a snapshot of predictive ability while ignoring the fluid nature of online interactions. In a live environment, comments arrive in a continuous and unpredictable stream, meaning a model’s latency becomes just as important as its accuracy. When a model makes a mistake—either by missing a toxic slur or by unfairly censoring a polite user—the error is not merely a statistical data point on a spreadsheet. It is a tangible event that can drive users away from a platform, directly impacting advertising revenue and community growth. The researchers argue that these “offline” metrics fail to capture the long-term consequences of moderation decisions, such as user attrition or the degradation of the conversational atmosphere. Consequently, a model that performs exceptionally well in a controlled lab setting might actually cause financial harm when deployed in a high-traffic ecosystem.
The PDS framework redefines content moderation as a business-critical engineering challenge rather than a simple mathematical problem. By accounting for the financial costs associated with both false negatives and false positives, the framework offers a pragmatic look at machine learning performance that aligns with corporate goals. A false negative, which allows toxic content to persist, creates user distress and potential churn, while a false positive stifles expression and alienates the user base. Each of these outcomes carries a specific monetary value based on projected lifetime user value and engagement levels. This shift in perspective allows platform operators to see the hidden costs of AI errors that were previously masked by high accuracy scores. Furthermore, it highlights the importance of balancing aggressive filtering with the need for vibrant, open discussion. By quantifying these variables, the study provides a roadmap for organizations to optimize their safety protocols without sacrificing their bottom line.
Methodology: Creating a Living Social Ecosystem
To validate their new approach, the research team constructed a sophisticated simulation involving 10,000 synthetic users interacting within a digital environment. This setup mirrors a week of continuous social engagement, where users post content, read messages, and react to one another while being subjected to AI-driven moderation. The PDS framework is highly customizable, allowing researchers to adjust variables such as toxicity concentration and user sensitivity to specific types of abuse. This flexibility makes it possible to see how different demographics react to various levels of intervention, providing insights that a static dataset could never offer. For instance, a community of gamers might have a higher tolerance for competitive banter compared to a professional networking site, and the simulation can reflect these nuances. By creating a “living” ecosystem, the researchers were able to observe the dynamic feedback loops that occur when moderation decisions influence future user behavior, providing a much deeper understanding of AI impact.
During the testing phase, the study applied eight distinct deep learning architectures to the simulation, ranging from simple convolutional neural networks to massive transformer models like RoBERTa. By observing these models in a controlled yet dynamic setting, the team tracked how computational throughput and processing delays affected the overall user experience. This methodology highlights the “ripple effects” of classification, demonstrating how a single moderation choice can influence a user’s subsequent posts and the general “temperature” of the digital space. The simulation revealed that high-latency models, even if highly accurate, can frustrate users by delaying the appearance of their comments or reactions. These delays break the real-time feel of a conversation, which is a primary driver of engagement on modern platforms. Consequently, the research suggests that the speed at which a model processes data is often just as vital for platform health as the precision of its toxicity detection, especially during peak traffic hours.
Architectural Trade-offs: Matching Models to Environments
One of the most significant findings from the research is the realization that there is no “perfect” AI model for every situation; instead, the ideal choice depends on the specific environment. In low-toxicity spaces, such as private family networks or niche hobbyist groups, lightweight models with high processing speeds were found to be superior. Because abusive language is relatively rare in these settings, the minor gains in accuracy provided by massive, expensive transformer models do not justify the high computational costs or the slower response times. In these cases, a simpler model like BERT-tiny or FastText can provide sufficient safety while maximizing platform efficiency and reducing the strain on server infrastructure. This allows small to medium-sized platforms to implement effective safety measures without requiring the massive hardware budgets of larger tech giants. Ultimately, the study encourages a more tailored approach to AI deployment, where the complexity of the tool matches the actual risk level of the community it serves.
Conversely, in high-toxicity environments where hostile content is rampant, the sheer volume of incoming data makes heavy transformer models like RoBERTa almost entirely impractical. The simulation demonstrated that these large-scale models create significant bottlenecks and latency issues that quickly degrade the user experience during high-traffic periods. In these high-pressure scenarios, fast and reasonably accurate models proved to be the most effective choice for maintaining order. While they might miss a small percentage of toxic comments that a larger model would catch, they ensure that the moderation queue does not back up and stall the platform’s functionality. When a system is overwhelmed by data, the “perfection” of a slow model becomes a liability that can lead to a total breakdown in user engagement. Therefore, for platforms dealing with high volumes of volatile content, the research advocates for prioritizing agility and throughput to keep the community active while still filtering out the most egregious forms of abuse.
The Economic Scorecard: Beyond Technical Accuracy
The PDS framework provides a holistic scorecard that translates technical performance into clear business logic for both executives and software engineers. A major takeaway for industry leaders in 2026 is that the most accurate model on a public leaderboard is often a poor choice for real-time industrial deployment. Large-scale models require immense hardware resources, including specialized GPUs and high energy consumption, which can significantly increase operational overhead. Furthermore, the introduction of lag can disrupt the real-time feel of a social network, leading to a noticeble drop in user engagement that far outweighs the benefits of a slightly higher precision rate. By using this profit-driven approach, platform operators can now perform a detailed cost-benefit analysis before deciding which system to roll out. This ensures that the technical choices made by the engineering team are aligned with the financial interests of the company, leading to more sustainable growth and better resource management.
Beyond just saving on infrastructure costs, the profit-driven evaluation method focuses on long-term user retention as a key indicator of success. The research showed that platforms using the PDS framework could better identify the “sweet spot” where moderation is strict enough to prevent harassment but flexible enough to encourage open dialogue. When users feel that a platform is well-moderated without being over-censored, their lifetime value increases, leading to more stable advertising revenue and a healthier ecosystem. This balance is difficult to achieve using traditional metrics alone, as they do not account for the emotional and social reactions of the user base. By integrating financial projections with toxicity detection, platforms can choose tools that balance agility with safety, ensuring that their moderation strategy supports the bottom line. This research empowers decision-makers to justify their AI investments by showing clear correlations between model performance and the actual health of their digital communities.
Future Implications: Grounding Artificial Intelligence in Reality
This research signals a broader shift toward “operationally grounded evaluation” in the field of artificial intelligence and machine learning. For years, the academic community has prioritized incremental gains in accuracy scores, often ignoring the practical context and constraints in which these models must operate. The PDS framework challenges this status quo by emphasizing that user dynamics, server costs, and environmental context are just as vital as the underlying code. By bridge-building between high-level data science and the practical needs of the technology industry, the Concordia and McGill researchers have created a new standard for how AI should be tested and deployed. This approach encourages developers to think about AI as a component of a larger system rather than a standalone tool. As we move through 2026, the focus is increasingly on building systems that are not just “smart” in a theoretical sense, but are also robust, efficient, and capable of operating under the stresses of the real world.
In conclusion, the development of the Profit-Driven Simulation framework successfully demonstrated that effective content moderation is a complex engineering discipline. The researchers provided a scalable path for platforms to improve their digital spaces by quantifying the direct relationship between AI performance and economic viability. The work served as a critical reminder that the most effective AI is not necessarily the one with the highest complexity, but rather the one that serves its users and the organization most efficiently. Looking forward, the team planned to expand the framework to include more diverse languages and complex psychological profiles to further refine the simulation’s accuracy. These future advancements will likely integrate reinforcement learning to help AI models adapt in real-time to changing user behaviors and emerging linguistic trends. By prioritizing practical outcomes over abstract technicality, the PDS framework established a new foundation for building safer and more profitable digital environments for millions of users worldwide.