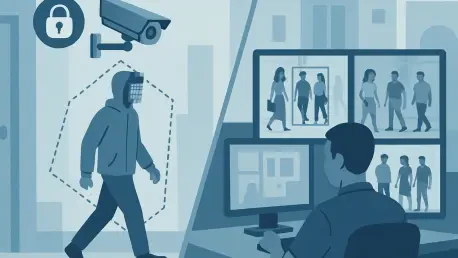
Relying on a single-shot estimator like MediaPipe BlazePose allows the system to extract coordinates for 33 body landmarks while stripping away identifiable textures. This approach, pioneered by researchers at the Vellore Institute of Technology through the development of the P2-VGAN architecture, represents a monumental shift in how automated surveillance systems operate in a modern, data-sensitive landscape. In the current climate of 2026, the demand for security remains high, yet traditional methods of constant video recording have become increasingly incompatible with ethical standards and legal frameworks. The Privacy-Conscious Velocity-Weighted Graph Attention Network, or P2-VGAN, offers a solution that treats human activity as geometric data rather than a collection of identifiable visual features. This strategic pivot addresses the core tension between the necessity for public safety and the fundamental right to individual privacy. By moving away from pixel-heavy analysis, the framework provides a pathway for deploying intelligent monitoring tools that are both effective and respectful of the populations they serve, marking a significant milestone in the evolution of computer vision technology.
Overcoming Hardware Constraints and Ambiguity
Traditional vision architectures that rely on dense three-dimensional convolutional networks or spatio-temporal transformers often face a steep uphill battle when deployed on the “edge.” These models typically contain tens of millions of parameters, requiring massive throughput that far exceeds the capabilities of standard commodity microprocessors found in typical municipal or commercial settings. In many cases, this forces a reliance on centralized cloud servers, which creates significant bandwidth strain and introduces vulnerabilities during data transmission. P2-VGAN circumvents these hardware limitations by utilizing a skeletal representation that significantly reduces the amount of data being processed at any given time. This allows the system to function efficiently on local hardware, such as an Intel Core i7 processor, without the need for expensive, energy-hungry graphics accelerators. The efficiency gained here is not just about saving power; it is about making sophisticated security tools accessible to organizations that cannot afford a massive high-end computing infrastructure for every camera node.
Beyond hardware hurdles, there is the persistent technical challenge of “kinematic ambiguity,” where a model struggles to differentiate between benign high-energy actions and genuine violence. A person sprinting to catch a departing bus or an individual waving enthusiastically to a friend can often trigger false alarms in conventional systems because the physical displacement looks similar to a criminal fleeing a scene or a physical altercation. Standard neural networks that aggregate spatial features uniformly across time often fail to recognize the subtle differences in limb coordination and acceleration that define these distinct behaviors. P2-VGAN addresses this by utilizing a lightweight pipeline that focuses specifically on the dynamics of human movement. By extracting body landmarks and analyzing them through a structured graph, the system can better interpret the functional relationships between joints, allowing for a more nuanced understanding of intent that simple pixel-tracking methods often miss entirely.
The Mechanics of Velocity-Weighted Attention
The primary technical innovation within the P2-VGAN architecture is its unique velocity-weighted attention mechanism, which is specifically designed to eliminate the noise of non-violent movement. This module calculates the velocity of each joint using first-order finite differences between sequential frames, creating a dynamic map of physical acceleration. By applying a mathematical structure that incorporates a softplus formulation and a sigmoid activation function, the network can automatically assign a higher “attention score” to rapidly moving extremities. This means that when the system analyzes a scene, it prioritizes the high-velocity movements typically associated with punches, kicks, or falls, while simultaneously dampening the influence of stationary or slow-moving body parts. This selective focus allows the model to cut through the complexity of a crowded visual field, pinpointing the exact kinetic signatures of an incident without being distracted by the background motion of a normal urban environment.
To further refine the accuracy of its detections, the framework incorporates a temporal pyramid network that evaluates patterns across multiple timescales. This multi-scale approach is vital for identifying both sudden, explosive bursts of aggression and more prolonged, abnormal sequences of behavior that might develop over several seconds. By pooling features across various dilation rates, the model gains a comprehensive view of how an event unfolds, from the initial high-velocity contact to the subsequent movement patterns. This hierarchical reasoning allows the system to maintain a high degree of sensitivity to anomalies while keeping false-positive rates low. The final output is processed by a linear classification head that determines the probability of a violent or abnormal event, providing a level of sophisticated reasoning that transforms a simple camera into a proactive safety tool capable of making real-time decisions without human intervention.
Aligning With Modern Privacy Standards
One of the most compelling reasons for the adoption of the P2-VGAN framework is its inherent alignment with modern data protection regulations, most notably the principles of “data minimization” outlined in the GDPR. In the legal landscape of 2026, organizations face increasing scrutiny regarding how they handle personal biometric data, and the penalties for mismanagement are severe. P2-VGAN addresses these concerns by design, as it only processes raw video transiently in local memory. Once the system extracts the necessary landmark coordinates, it immediately releases the references to the decoded visual pixel arrays. This means that the system never stores or transmits identifiable images of faces, skin tones, or clothing. Instead, it works entirely with a numerical matrix of geometric points, which is a far more privacy-conscious representation. This systematic removal of visual surface textures effectively mitigates the greatest liabilities associated with long-term surveillance.
By enforcing this edge-level visual data minimization, the framework essentially creates a “privacy firewall” at the point of capture. Because the system does not require raw footage to be sent to a central server for analysis, the risk of a catastrophic data breach involving sensitive personal imagery is virtually eliminated. This approach not only protects the individuals being monitored but also provides a robust legal defense for the organizations deploying the technology. They can demonstrate that they are taking active steps to minimize the collection of personal data while still fulfilling their duty to maintain a safe environment. Researchers emphasize that while this skeletal approach is not a cryptographic guarantee of total anonymity, it represents a significant step forward in making public safety measures compatible with the growing global consensus on the importance of individual digital privacy.
Analyzing Benchmarks and Empirical Success
The effectiveness of the P2-VGAN model was thoroughly validated through rigorous testing against the ShanghaiTech Campus dataset, which is a standard benchmark for evaluating weakly supervised anomaly detection. In these evaluations, the architecture achieved a frame-level area under the curve (AUC) of 84.72%, demonstrating a high level of reliability in identifying abnormal events in complex campus environments. When the results were compared to a baseline Graph Attention Network that lacked velocity-weighted gating, researchers observed a clear and statistically significant improvement in performance. This confirmed that the addition of kinematic weight was not just a theoretical improvement but a practical one that directly enhanced the model’s ability to distinguish between normal and abnormal activity. The consistency of these results across multiple random seeds suggests that the model is robust and capable of maintaining its accuracy across different physical settings.
A series of ablation studies further highlighted the importance of each component within the P2-VGAN architecture. For instance, the inclusion of continuous adjacency weights, which allow the network to learn functional relationships between non-connected joints, raised the baseline accuracy from approximately 79% to over 81%. However, it was the velocity-weighted attention module that provided the most substantial single boost, pushing the accuracy toward the mid-80s. These findings illustrate that while individual components like graph reasoning and temporal pooling are valuable, it is their integration with kinematic velocity data that makes the system truly effective. Researchers also found that simpler methods, such as basic coordinate filtering, were woefully inadequate for real-world scenarios, yielding accuracy rates that were too low for practical security applications. This reinforces the idea that sophisticated, multi-layered reasoning is essential for reliable automated surveillance.
Performance Across Varied Crime Scenarios
While the P2-VGAN model excels in many areas, its performance varies depending on the specific nature of the anomaly it is attempting to detect. When tested on the diverse UCF-Crime dataset, the model showed exceptional proficiency in identifying high-motion events such as fighting and physical assaults, achieving detection rates of 83.1% and 82.4%, respectively. This is largely because these types of crimes involve the specific high-velocity limb movements that the gating mechanism was designed to prioritize. For security personnel, this means the system is particularly well-suited for early intervention in violent altercations where every second counts. The ability to automatically flag a fight as it starts, without requiring a human operator to be watching that specific camera at that specific moment, represents a major advancement in the proactive capabilities of modern public safety systems.
However, the transition from high-motion violence to low-motion criminal activity reveals some of the inherent limitations of a skeleton-based approach. The detection rates for vandalism, robbery, and stealing were noticeably lower, ranging from 71.7% to 76.5%. This discrepancy exists because these crimes often rely on semantic intent or interactions with objects rather than dramatic physical movement. For example, a person picking a pocket may maintain a very normal walking posture, making their skeletal landmarks indistinguishable from those of any other pedestrian. Without access to pixel-level details of the objects being manipulated, the model struggles to identify the anomaly. This highlights a fundamental trade-off in the design of P2-VGAN: by choosing to protect privacy by stripping away visual textures, the system sacrifices its ability to detect crimes that do not have a distinct kinematic signature, suggesting that it should be used as part of a broader, multi-layered security strategy.
Infrastructure Requirements and Real-Time Speed
One of the standout features of the P2-VGAN architecture is its ability to deliver high-performance results on standard computing hardware, which is a critical factor for large-scale urban deployment. In performance testing on a common Intel Core i7-10700 processor, the system maintained an impressive end-to-end processing speed of 34.01 frames per second. This frame rate is more than sufficient for real-time monitoring, as it exceeds the standard 30 FPS output of most modern security cameras. The breakdown of latency shows that the majority of the processing time—about 18.40 milliseconds—is dedicated to the initial pose extraction, while the downstream graph reasoning takes only 11.01 milliseconds. With a total per-frame latency of less than 30 milliseconds, the system can operate with zero perceptible lag, providing security teams with instant alerts as events occur.
This level of efficiency is made possible by the model’s lean architectural design, which utilizes only 1.8 million trainable parameters. This is a fraction of the size of the massive vision models often touted in academic circles, which can easily reach 50 million or 100 million parameters. By focusing on a “Pareto-efficient” design, the P2-VGAN researchers have created a system that maximizes its detection capabilities while minimizing its consumption of electricity and computational cycles. This makes the technology highly sustainable and cost-effective for long-term use. Instead of investing in massive data centers and specialized cooling systems for GPU clusters, organizations can implement this AI-driven surveillance on the same desktop computers they already use for basic operations. This democratizes access to advanced security tools and ensures that even smaller municipalities can benefit from the latest developments in artificial intelligence.
Strategic Recommendations and Future Directions
The development of P2-VGAN has opened the door to a more ethical and efficient future for smart surveillance, but it has also identified key areas where further research is necessary to achieve total reliability. One significant challenge that remains is the issue of “occlusion,” which happens when a person is partially hidden by a wall, a vehicle, or a dense crowd. Because the system relies on landmarks, its accuracy drops significantly when those landmarks cannot be accurately placed due to visual obstructions. Researchers noted that solving this problem will require more advanced graph completion techniques that can use AI to “guess” the location of hidden joints based on the movement of visible parts of the body. Addressing this gap will be crucial for making the system effective in the highly crowded urban environments where surveillance is often most needed.
Another important consideration for the future is the potential for re-identification through gait analysis. While P2-VGAN strips away facial features and clothing, an individual’s movement trajectory can still be unique enough to serve as a biometric identifier in some contexts. To stay ahead of these privacy concerns, the next steps in research involve exploring federated learning models. This would allow the system to be trained across a vast network of camera nodes without the raw data ever being shared or centralized, providing an additional layer of security for the information being processed. Furthermore, finding a way to integrate minimal object-interaction data without re-introducing privacy-invasive pixel analysis remains a high priority. By finding this middle ground, the next generation of this technology could offer comprehensive protection against both violent and non-violent crimes while remaining fully committed to the principles of data minimization and citizen privacy.
Finalizing Sustainable Surveillance Strategies
The research team successfully demonstrated that high-performance anomaly detection did not require the sacrifice of personal privacy or the utilization of expensive, specialized hardware. By engineering a velocity-weighted attention mechanism into a lightweight graph network, the study proved that architectural ingenuity could effectively bridge the gap between safety and civil liberties. The implementation of P2-VGAN showed that it was possible to maintain real-time monitoring speeds on standard processors, which significantly lowered the barrier to entry for many public safety organizations. The results achieved on the ShanghaiTech and UCF-Crime datasets provided a clear benchmark for how skeleton-based models could be utilized to detect physical violence with a high degree of accuracy. This study served as a vital proof-of-concept for a new era of “smart” infrastructure that was designed to be responsible and efficient from the ground up.
As a result of these findings, it was established that organizations should prioritize the transition toward edge-based processing to comply with evolving data protection laws. The study concluded that developers had to focus on improving graph completion to manage the complexities of urban occlusion and suggested that future systems should incorporate federated learning to further decentralize data handling. It was also determined that while pose-based detection was a powerful tool for intervening in violent crimes, it was most effective when used as one component of a holistic safety strategy. The success of the P2-VGAN project provided a clear roadmap for the deployment of ethical AI in public spaces, ensuring that the benefits of automated surveillance could be realized without compromising the trust of the community. Moving forward, the focus remained on refining these lightweight models to handle a wider range of scenarios while maintaining their commitment to the fundamental principles of data minimization.