When a mission-critical database experiences a sudden failure, the only thing more catastrophic than the downtime itself is the realization that the monitoring system meant to flag the issue has also quietly gone offline. This paradox of observability has long haunted DevOps teams, but the arrival of Percona Monitoring and Management High Availability (PMM HA) marks a significant shift toward absolute resilience in the database ecosystem. For years, the monitoring server remained a single point of failure, often trailing behind the high-availability standards of the databases it supervised. Now, this update ensures that the “watchman” is just as robust as the assets under its care.
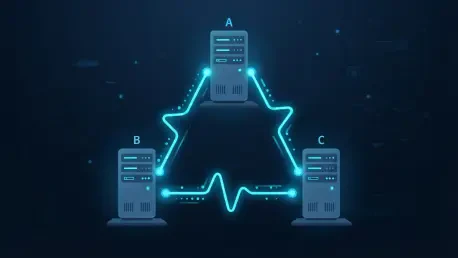
The core subject of this development is the transition of database monitoring from a single-instance vulnerability to a robust, Kubernetes-native service. PMM HA operates by running three PMM servers behind a single address. In the event of a server, pod, or node failure, the system automatically triggers a leader election, allowing a new server to take over in seconds. This failover process is transparent to users and connected services, as clients and browsers continue to use the same endpoint without requiring manual reconfiguration or re-authentication.
Assessing the Strategic Value of PMM High Availability
Transitioning from a single-instance to an HA architecture is no longer just a luxury for the risk-averse; it is a fundamental requirement for modern enterprises operating in 2026. As organizations scale their data layers, the cost of a “blind spot”—where a database fails while the monitoring tool is down—becomes astronomically high. PMM HA addresses this by ensuring that observability matches the uptime of the underlying clusters, creating a unified standard for infrastructure reliability.
Moreover, the shift eliminates the traditional single point of failure that has historically compromised monitoring integrity. By maintaining continuous database oversight, companies can avoid the reputational and financial damage associated with undetected performance degradation. This transition justifies the investment for any enterprise that prioritizes high-availability databases, as the monitoring stack finally reflects the same level of operational maturity.
Technical Overview of the PMM HA Architecture
The move to a Kubernetes-native service defines the modern deployment model, utilizing a resilient three-node configuration that leverages specialized operators and Helm charts. This architecture facilitates a rapid leader election process; if one node fails, a new leader takes over within seconds without requiring manual intervention. Users interact with a single-address endpoint, making the failover entirely transparent to connected browsers and clients.
Furthermore, the inclusion of ARM64 support allows teams to deploy this robust stack across diverse hardware environments, including cost-effective cloud instances. Validated on platforms like Amazon EKS and Red Hat OpenShift, the system provides high portability for hybrid-cloud strategies. These technical advancements ensure that the infrastructure remains both flexible and performant across the current monitoring landscape from 2026 to 2028.
Evaluating Real-World Performance and Reliability
One of the most significant advantages of this release is the elimination of silent outages. In traditional setups, a monitoring failure stops all alert rules, but the HA model ensures that alerting continuity is maintained even during server swaps. Data integrity is further protected through a sophisticated client-side queuing mechanism. If the connection to the server is interrupted, the client stores metric data locally and transmits it once the path is restored.
Maintenance orchestration also sees a major upgrade, as the system supports rolling updates and sequential replica replacement. This allows for zero-downtime upgrades of the monitoring stack itself. Additionally, the integration of S3-compatible backup and disaster recovery orchestration provides an extra layer of safety, ensuring that historical performance data remains available even in the event of a total cluster catastrophe.
Weighing the Strengths and Limitations of the HA Release
Adopting PMM HA provides high resilience without the frustration of re-authentication or manual failover procedures. It upholds the commitment to open-source database observability while significantly reducing the risk of data loss. The platform effectively bridges the gap between infrastructure reliability and metric visibility, ensuring that the monitoring layer is never the weakest link in the production chain.
However, this level of reliability comes with increased infrastructure complexity and higher resource requirements compared to a single-node setup. Teams must also navigate a steeper learning curve associated with Kubernetes, which might be a hurdle for organizations still relying on legacy virtual machine environments. Despite these challenges, the trade-off remains favorable for those who require 24/7 database uptime and comprehensive historical data.
Summary of Findings and Adoption Recommendations
The introduction of PMM 3.10.0 significantly stabilizes the observability layer for mission-critical workloads. For organizations managing large-scale production databases where even a few minutes of lost metrics can derail troubleshooting, the transition to the HA version is highly recommended. The platform currently stands as a mature solution for high-traffic environments that cannot afford gaps in their performance telemetry.
Smaller deployments might find the overhead of a three-node cluster unnecessary, but for any enterprise-grade operation, the reduction in operational risk justifies the additional resources. The current trajectory of the platform indicates a strong focus on self-healing capabilities and cloud-native integration. Decision-makers should evaluate their current downtime tolerance to determine if the jump to a clustered architecture aligns with their service-level objectives.
Final Verdict: Is PMM HA Right for Your Infrastructure?
DevOps and SRE teams managing high-traffic environments viewed PMM HA as the new baseline for professional database management. The shift toward a distributed monitoring model provided a necessary layer of protection against hardware failures and network partitions that previously crippled visibility. Strategic planning for the remainder of 2026 focused on auditing existing monitoring stacks and identifying where the lack of redundancy created systemic vulnerability.
Implementing this solution allowed teams to move toward a more proactive maintenance cycle, where the monitoring tools themselves finally achieved the same tier of reliability as the production databases. Future considerations included the potential for further hardware diversification and the integration of more automated disaster recovery protocols. Ultimately, the transition to a high-availability monitoring stack proved to be a critical step for organizations striving for total infrastructure resilience.