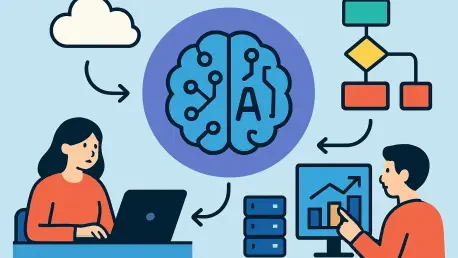
Modern enterprise AI agents frequently crash against the invisible walls of fragmented relational databases, where thousands of disconnected tables turn simple business questions into expensive computational nightmares. While these autonomous entities possess the reasoning capacity of a seasoned analyst, they often falter at the foundational level of data retrieval. The persistent friction between advanced language models and rigid SQL structures has created a bottleneck that threatens to stall the momentum of corporate automation initiatives. As organizations pivot toward agentic workflows, the primary challenge is no longer the intelligence of the underlying model but rather the accessibility and coherence of the data it is asked to navigate.
The arrival of PuppyGraph 1.0 introduces a compelling alternative to traditional data management by proposing a unified graph layer that operates without moving a single byte of information. This technology seeks to treat an entire data lakehouse as a single, interconnected graph, allowing AI agents to perceive relationships rather than just rows and columns. By abstracting the complexity of the underlying warehouse, the platform aims to reduce the common phenomenon of “hallucinated” connections that occur when models attempt to guess how disparate tables relate to one another. This shift marks a significant step toward more seamless integration of data infrastructure and autonomous reasoning.
Beyond the Join: Why AI Agents Are Struggling With Your Data Warehouse
The promise of autonomous AI agents often hits a practical wall when confronted with the reality of enterprise data architectures. In a typical corporate environment, critical information is buried under layers of complex relational structures, requiring intricate SQL joins to extract even basic insights. When an AI agent is tasked with answering a business question, it must dynamically generate these queries on the fly. However, as the depth of the required joins increases, the probability of the agent making a logic error rises exponentially. This leads to a cycle of failed queries and incorrect answers that undermines the reliability of the entire AI system.
Furthermore, the computational cost of these failures is becoming a significant burden for IT budgets. Every time an agent fails to retrieve the correct data, it often attempts to retry the operation with a modified query, consuming expensive large language model tokens and database compute cycles in the process. This “trial and error” approach to data retrieval is not only inefficient but also slow, resulting in high latency that makes real-time interaction nearly impossible. The sheer weight of relational complexity acts as a tax on innovation, forcing developers to spend more time debugging data access paths than refining the agent’s actual reasoning capabilities.
Historically, the only way to solve these relationship-heavy problems was to move data into a dedicated graph database. This process created a “data duplication trap” where organizations were forced to build and maintain expensive ETL pipelines to keep the graph database in sync with the primary data warehouse. These redundant silos added layers of operational overhead and increased the risk of data inconsistency. PuppyGraph 1.0 seeks to break this cycle by allowing graph analysis to occur directly where the data lives. By providing a graph-based view of existing relational tables, it eliminates the need for data movement while providing the interconnected perspective that AI agents require.
The Data Fragmentation Crisis in the Age of Agentic AI
To understand the necessity of a graph-centric approach, one must examine the growing rift between the needs of modern language models and the constraints of traditional storage. LLMs are inherently better at understanding nodes and relationships than they are at navigating abstract table schemas with dozens of foreign keys. When data is fragmented across disparate silos, the agent lacks a holistic “map” of the business landscape. This lack of context forces the model to rely on its training data or flawed schema interpretations, which is exactly where hallucinations begin to creep into the workflow.
The cost of this fragmentation is not just measured in compute credits but in the erosion of trust between the business and its AI initiatives. If an agent provides a financial insight that is based on a misjoined table, the resulting error can have significant strategic consequences. Moreover, the manual effort required to “hard-code” every possible relationship into an agent’s prompt is a task that does not scale. As the volume of data grows from 2026 to 2028, the difficulty of maintaining these manual connections will likely become the single greatest barrier to achieving true agentic autonomy within the enterprise.
In contrast to the siloed approach, a graph overlay provides a semantic bridge that translates relational data into a language the AI can better process. This move toward a more “natural” data structure allows agents to perform multi-hop reasoning—tracing a customer’s journey from a marketing click to a support ticket and finally to a renewal—without getting lost in the underlying SQL syntax. By centering the data architecture on relationships, organizations can ensure that their AI systems are working with a unified version of the truth, rather than a collection of scattered data points that may or may not fit together correctly.
Breaking Down PuppyGraph 1.0: Features Designed for Automation
The 1.0 release introduces a suite of tools specifically engineered to bridge the gap between raw data warehouses and autonomous AI systems. A primary highlight is the AI-assisted graph schema builder, which automates the traditionally labor-intensive task of mapping relational tables to graph nodes and edges. Instead of requiring a data engineer to manually define every link, the tool scans the existing lakehouse and suggests a logical graph structure. This allows developers to quickly establish the business logic that AI agents need to follow, drastically reducing the time required to move from a raw dataset to a functional agentic workflow.
Another significant development is the integration with the Model Context Protocol (MCP), an emerging standard that simplifies the connection between data infrastructure and AI ecosystems. By supporting this protocol, PuppyGraph becomes a “pluggable” component that can easily communicate with various agent development frameworks. This eliminates the need for custom “glue code” and allows engineers to swap models or tools without rebuilding their entire data access layer. The focus on interoperability ensures that the graph engine can serve as a consistent foundation even as the surrounding AI landscape continues to evolve.
To maintain the integrity of the data, the platform utilizes what experts call an “enforced ontology” gatekeeper. Unlike a raw SQL interface that might accept any logically sound join, this engine validates agent queries against a predefined graph schema. If an agent attempts to request a relationship that does not exist in the actual business data, the gatekeeper rejects the query and provides the agent with feedback to correct its course. This mechanism forces the AI to remain grounded in verified facts. Furthermore, a distributed compute engine handles the heavy lifting of multi-hop queries, using parallel execution to maintain high performance without the latency penalties associated with traditional nested joins.
Expert Perspectives on the Shift to Graph-Centric Data Layers
Industry analysts have observed a clear trend toward the consolidation of data tools, a movement that PuppyGraph 1.0 seems uniquely positioned to capitalize on. Market research from IDC indicates that 96% of organizations are actively seeking ways to simplify their data management stacks. Analysts suggest that by enabling graph analysis directly within popular environments like Snowflake, Databricks, or Microsoft Fabric, the platform helps companies avoid the proliferation of specialized databases. This strategic alignment with existing infrastructure makes it an attractive option for CIOs looking to maximize their current cloud investments while adding advanced AI capabilities.
However, some experts point out that while the tool simplifies the querying process, it does not entirely eliminate technical complexity. Michael Leone, a prominent analyst at ESG, has noted that the burden often shifts from the query phase to the initial design and governance of the graph model. Defining the right ontology is a critical step that still requires a deep understanding of the business domain. The tool makes the mapping easier, but the strategic decision of how nodes and edges should be structured remains a human-led endeavor. This highlights the importance of data governance as a prerequisite for successful AI integration.
There are also practical considerations regarding infrastructure sensitivity and operational costs. Experts such as Ashish Chaturvedi from HFS Research have warned that because the engine queries data in its native location, high-intensity graph workloads could lead to increased credit consumption on the underlying warehouse platform. Organizations must be diligent in monitoring how these complex traversals impact their overall cloud spending. Despite these concerns, early adoption by high-profile firms like Palo Alto Networks and Coinbase suggests that the market is ready for tools that prioritize interconnected data analysis, especially when they can be deployed within a modern, governed environment.
Implementing PuppyGraph 1.0: A Framework for Enterprise Integration
For organizations ready to streamline their AI workflows, the transition to a graph-overlay approach requires a structured and deliberate strategy. The first step involves identifying specific relational bottlenecks within the existing infrastructure—locating the use cases where AI agents are currently failing due to complex SQL joins or high error rates. By targeting these friction points first, teams can demonstrate the immediate value of the graph engine. Once these areas are identified, the AI-assisted schema builder can be used to scan the relevant tables and suggest a mapping that reflects the actual business rules of the organization.
The next phase of the framework focuses on connectivity and monitoring. Utilizing the Model Context Protocol allows the development team to link the graph engine directly to their preferred agent frameworks, ensuring a standardized flow of information. However, it is vital to implement robust monitoring to track the performance and cost of these operations. Since the engine leverages the compute power of the underlying warehouse, tracking the cost per query becomes essential to prevent budget overruns. Using modern orchestration tools like Docker or Kubernetes ensures that the query engine is integrated into the existing cloud environment with minimal friction.
Finally, the success of the integration depends on a culture of continuous refinement. As business needs change, the graph schema must be updated to reflect new entities and relationships. This iterative process ensures that the AI agents always have an accurate and up-to-date map of the enterprise data. By maintaining a clear ontology and leveraging the parallel execution capabilities of the distributed engine, companies can build a data layer that is not only robust enough for today’s challenges but also flexible enough to support the next generation of autonomous systems.
The implementation of PuppyGraph 1.0 marked a transition toward a more logical and efficient intersection of data and artificial intelligence. Organizations that adopted the platform successfully reduced the time spent on manual data engineering and saw a measurable decrease in the error rates of their AI agents. By choosing to bridge the gap between relational storage and graph-based reasoning, these firms avoided the high costs of data duplication and the pitfalls of siloed information. The strategy of using an overlay rather than a replacement proved to be a practical solution for a landscape that demanded both high performance and strict governance. Ultimately, the move toward a graph-centric architecture provided the clarity needed to turn fragmented data into a strategic asset for the modern enterprise.